 NERDICATE
Lasso vs. Ridge Regression
Discover how Lasso and Ridge regression prevent overfitting, understand the mathematics behind L1 and L2 regularization, and learn how to compare both methods using Python.
Lasso vs. Ridge Regression: Understanding L1 and L2 Regularization
Two models can learn from exactly the same data and produce very different solutions. The difference may come down to one mathematical idea: how much complexity are we willing to allow?
Imagine building a machine learning model that predicts house prices.
You give it information about the houses: their size, location, age, number of bedrooms, and other characteristics. The model learns relationships between these features and the final price.
At first, adding more information seems like a good idea. More features should help the model understand the problem better.
But there is a catch.
A model can become so focused on the training data that it starts learning noise instead of meaningful patterns. It performs exceptionally well on examples it has already seen but struggles with new data.
This is called overfitting.
One way to address this problem is to penalize excessive model complexity.
Two of the most important methods for doing this are Ridge Regression and Lasso Regression.
Both extend linear regression by adding a penalty to the objective function. However, they use different mathematical rules, and those differences can significantly affect the resulting model.
Understanding them will help you connect linear algebra, optimization, statistics, and practical machine learning.
1. The Problem: When a Model Learns Too Much
Let's begin with ordinary linear regression.
Suppose we want to predict a target value y using p features:
\hat{y} = w_0 + w_1x_1 + w_2x_2 + \cdots + w_px_p
Here:
- y is the actual target value.
- \hat{y} is the predicted value.
- x_1,\ldots,x_p are the input features.
- w_0 is the intercept.
- w_1,\ldots,w_p are the model coefficients.
The model learns the coefficients from the training data.
A common objective is to minimize the sum of squared prediction errors:
J(\mathbf{w}) = \frac{1}{n} \sum_{i=1}^{n} (y_i-\hat{y}_i)^2
In matrix notation, we can write this as:
J(\mathbf{w}) = \frac{1}{n} \|\mathbf{y}-X\mathbf{w}\|_2^2
where X is the feature matrix and \mathbf{w} contains the model coefficients.
The notation \|\cdot\|_2 represents the Euclidean norm.
The objective is straightforward: find coefficients that make predictions as close as possible to the observed values.
But minimizing training error alone does not guarantee good predictions on unseen data.
Why can this fail?
Imagine a model with many features:
- House size.
- Number of bedrooms.
- Number of bathrooms.
- Age of the building.
- Distance from the city centre.
- Local crime statistics.
- Dozens of additional measurements.
Some features may be useful. Others may contain little predictive information.
If the model assigns excessively large coefficients to weak or noisy features, its predictions can become unstable.
A small change in the input data may then produce a surprisingly large change in the prediction.
This is one reason why controlling model complexity matters.
2. The Basic Idea of Regularization
Regularization modifies the objective function by adding a penalty.
Instead of minimizing only the prediction error, we minimize:
J(\mathbf{w}) = \text{Prediction Error} + \text{Complexity Penalty}
The model must now balance two competing goals:
- Fit the training data well.
- Avoid unnecessarily large or complicated coefficients.
For linear regression, we can express this general idea as:
J(\mathbf{w}) = \frac{1}{n}\|\mathbf{y}-X\mathbf{w}\|_2^2 + \lambda R(\mathbf{w})
Here, R(\mathbf{w}) is the regularization penalty, and \lambda controls its strength.
When \lambda = 0, the penalty disappears, and we recover ordinary least squares.
As \lambda increases, the penalty becomes more influential.
The model is encouraged to use smaller coefficients, even if that means accepting slightly larger training errors.
This trade-off is central to regularization.
What does lambda actually do?
Consider three possible settings:
- Small \lambda: The model prioritizes fitting the training data.
- Moderate \lambda: The model balances fit and complexity.
- Large \lambda: The model strongly penalizes large coefficients and may become too simple.
The optimal value depends on the dataset.
Too little regularization may leave the model vulnerable to overfitting. Too much can cause underfitting.
The challenge is to find a useful balance.
This is where Ridge and Lasso take different paths.
3. Ridge Regression: L2 Regularization
Ridge Regression adds a penalty based on the squared coefficients.
Its objective function is:
J_{\text{Ridge}}(\mathbf{w}) = \frac{1}{n}\|\mathbf{y}-X\mathbf{w}\|_2^2 + \lambda\|\mathbf{w}\|_2^2
Expanding the penalty gives:
\|\mathbf{w}\|_2^2 = w_1^2+w_2^2+\cdots+w_p^2
Therefore:
J_{\text{Ridge}}(\mathbf{w}) = \frac{1}{n}\|\mathbf{y}-X\mathbf{w}\|_2^2 + \lambda\sum_{j=1}^{p}w_j^2
The intercept is conventionally excluded from the penalty.
The key idea is simple: large coefficients become increasingly expensive because their squares grow rapidly.
For example:
2^2=4
but:
10^2=100
A coefficient of 10 contributes much more to the penalty than a coefficient of 2.
Ridge therefore encourages the model to distribute predictive influence more conservatively.
What happens to the coefficients?
Ridge typically shrinks coefficients towards zero.
For example, an ordinary linear regression model might produce:
\mathbf{w} = \begin{bmatrix} 8.2\\ -4.5\\ 2.7\\ 0.9 \end{bmatrix}
After applying Ridge regularization, the coefficients might become:
\mathbf{w}_{\text{Ridge}} = \begin{bmatrix} 6.1\\ -3.2\\ 1.8\\ 0.5 \end{bmatrix}
These numbers are illustrative rather than the result of a particular dataset.
Notice that all four coefficients remain nonzero.
This is a characteristic tendency of Ridge: it reduces coefficient magnitudes but generally does not eliminate features entirely.
Why is Ridge useful?
Ridge is particularly useful when several features contain useful information and we want to reduce the sensitivity of the model to the training data.
It is also valuable when features are strongly correlated.
For example, suppose a housing dataset contains both the area of a house in square metres and the area in square feet.
These features provide almost the same information.
Ordinary least squares may produce unstable coefficients because the features are highly correlated.
Ridge can make the fitted coefficients more stable by penalizing large values.
However, it does not automatically determine which features are truly important.
It generally retains all features in the model.
4. Lasso Regression: L1 Regularization
Lasso Regression uses a different penalty.
Instead of squaring the coefficients, it penalizes their absolute values:
J_{\text{Lasso}}(\mathbf{w}) = \frac{1}{n}\|\mathbf{y}-X\mathbf{w}\|_2^2 + \lambda\|\mathbf{w}\|_1
The L1 norm is:
\|\mathbf{w}\|_1 = |w_1|+|w_2|+\cdots+|w_p|
Therefore:
J_{\text{Lasso}}(\mathbf{w}) = \frac{1}{n}\|\mathbf{y}-X\mathbf{w}\|_2^2 + \lambda\sum_{j=1}^{p}|w_j|
Again, the intercept is conventionally excluded from the penalty.
The important difference is that Lasso uses absolute values rather than squares.
This seemingly small change has a major consequence.
Lasso can drive some coefficients exactly to zero.
A coefficient that becomes zero no longer contributes to the model's prediction.
This means Lasso can perform a form of automatic feature selection.
An example of feature selection
Imagine that a model uses six features:
\mathbf{w} = \begin{bmatrix} 5.4\\ -3.1\\ 0.8\\ 2.7\\ 0.2\\ -1.6 \end{bmatrix}
After applying Lasso, the coefficients might become:
\mathbf{w}_{\text{Lasso}} = \begin{bmatrix} 4.2\\ -2.3\\ 0\\ 1.8\\ 0\\ -0.9 \end{bmatrix}
Again, these values are illustrative.
Two coefficients have become exactly zero.
The resulting model effectively excludes those two features.
Instead of merely reducing the magnitude of every coefficient, Lasso can produce a simpler model that uses only a subset of the available features.
Why is this useful?
Consider a dataset with hundreds or thousands of potential input features.
Some may contain useful predictive information. Others may be redundant or mostly noise.
Lasso can produce a sparse coefficient vector:
\mathbf{w} = \begin{bmatrix} w_1\\ 0\\ 0\\ w_4\\ 0\\ w_6 \end{bmatrix}
Only three coefficients are nonzero.
This can make the model easier to inspect and explain.
However, a zero coefficient does not necessarily prove that the corresponding feature is intrinsically useless. Feature selection depends on the dataset, the regularization strength, and the relationships between features.
When several features are strongly correlated, Lasso may select one and suppress others.
5. The Mathematical Difference: L1 vs. L2
Let's compare the two penalties directly.
For Ridge:
R_{\text{Ridge}}(\mathbf{w}) = \sum_{j=1}^{p}w_j^2
For Lasso:
R_{\text{Lasso}}(\mathbf{w}) = \sum_{j=1}^{p}|w_j|
Both discourage large coefficients, but they penalize them differently.
Consider a single coefficient.
| Coefficient w | L1 penalty |w| | L2 penalty w^2 |
|---|---|---|
| 0 | 0 | 0 |
| 1 | 1 | 1 |
| 2 | 2 | 4 |
| 3 | 3 | 9 |
| 5 | 5 | 25 |
| 10 | 10 | 100 |
The L2 penalty grows quadratically, while the L1 penalty grows linearly.
This means Ridge places a particularly strong penalty on very large coefficients.
Yet Lasso is the method associated with exact zeros.
Why?
The answer is not simply that the L1 penalty grows faster. It does not.
The difference comes from the geometry and optimization properties of the two penalties.
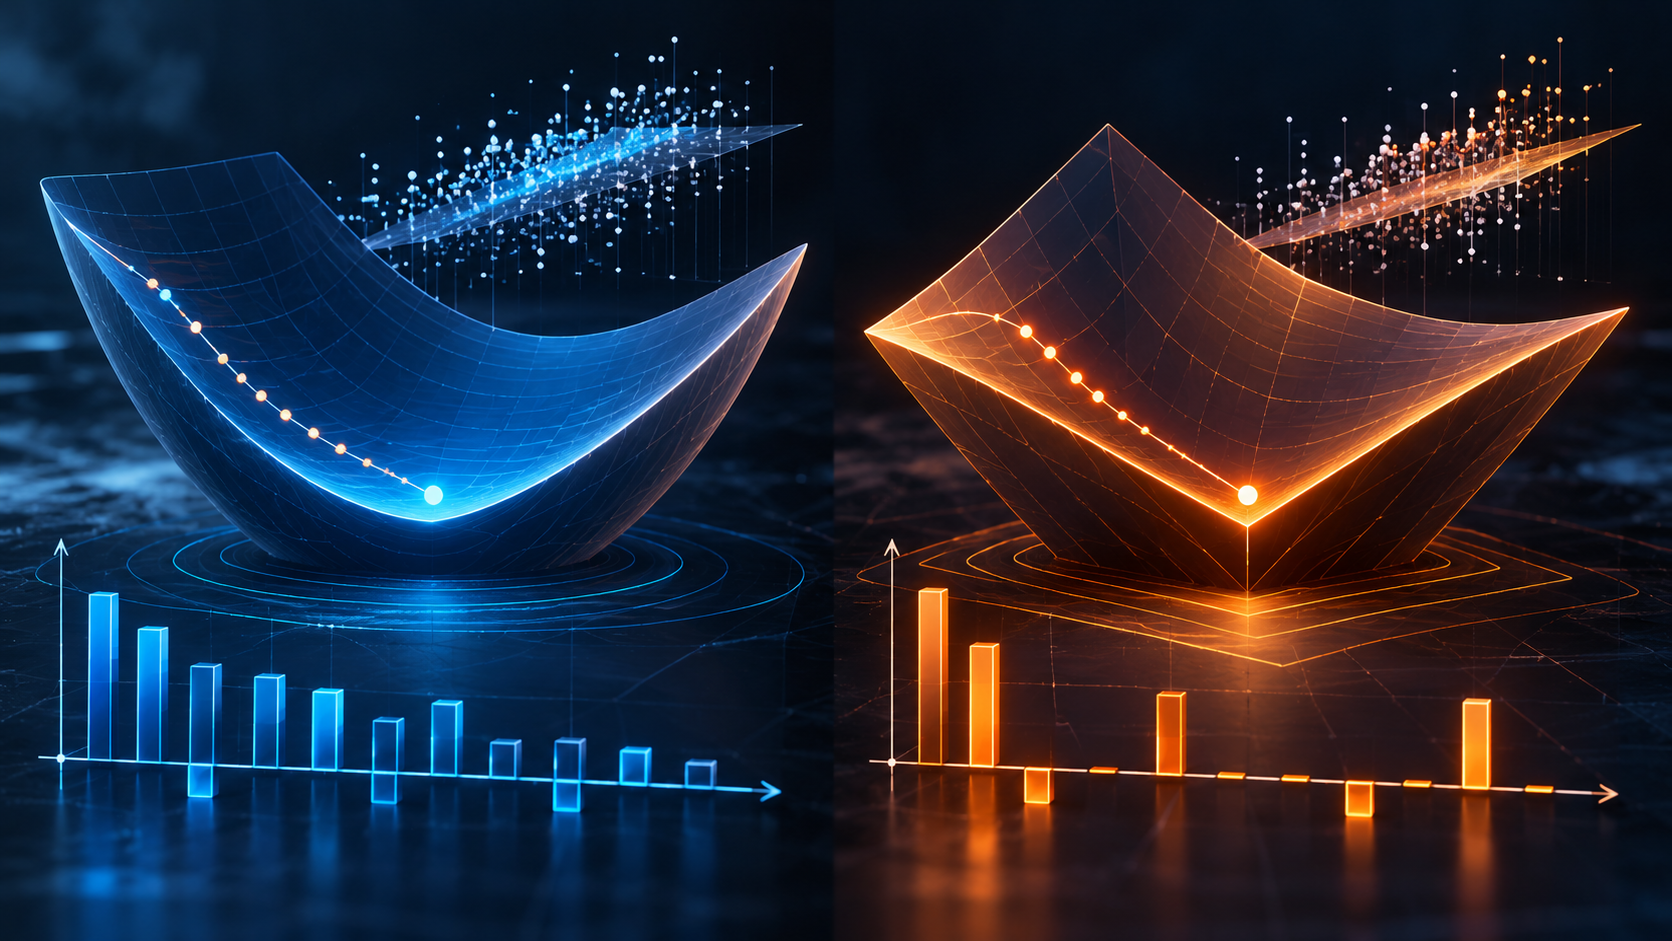
The geometric intuition
Imagine that we have two coefficients, w_1 and w_2.
The Ridge penalty defines circular contours:
w_1^2+w_2^2=c
The Lasso penalty defines diamond-shaped contours:
|w_1|+|w_2|=c
The least-squares objective also has contour lines representing different prediction errors.
Regularization finds a balance between these error contours and the penalty.
With Lasso, the diamond has corners on the coordinate axes.
Those corners correspond to solutions where one or more coefficients are exactly zero.
The optimum can occur at one of these corners, making sparse solutions more likely.
Ridge has smooth circular contours instead. Its optimum generally occurs with nonzero coefficients, although their values may become very small.
This geometric explanation captures the central distinction between L1 and L2 regularization.
6. A Small Numerical Example
Suppose we have a model with two coefficients and want to minimize the following simplified objective:
J(w_1,w_2) = (w_1-3)^2+(w_2-0.5)^2 +\lambda R(w_1,w_2)
The first part encourages the coefficients to approach 3 and 0.5.
The regularization term discourages complexity.
Let:
\lambda=1
Ridge solution
For Ridge:
R(w_1,w_2)=w_1^2+w_2^2
The objective is:
J_{\text{Ridge}} = (w_1-3)^2+(w_2-0.5)^2+w_1^2+w_2^2
Differentiate with respect to each coefficient:
\frac{\partial J}{\partial w_1} = 2(w_1-3)+2w_1
Set the derivative to zero:
2(w_1-3)+2w_1=0
Simplifying:
4w_1=6
Therefore:
w_1=1.5
For the second coefficient:
\frac{\partial J}{\partial w_2} = 2(w_2-0.5)+2w_2
Setting it equal to zero gives:
4w_2=1
Therefore:
w_2=0.25
The Ridge solution is:
\boxed{(w_1,w_2)=(1.5,0.25)}
Both coefficients remain nonzero.
Lasso solution
Now consider:
J_{\text{Lasso}} = (w_1-3)^2+(w_2-0.5)^2+|w_1|+|w_2|
For positive coefficients, the absolute-value terms have derivative 1.
For w_1>0:
2(w_1-3)+1=0
Therefore:
w_1=2.5
For w_2>0:
2(w_2-0.5)+1=0
This gives:
w_2=0
At zero, the absolute-value function is not differentiable in the ordinary sense. We can verify the optimum using the subgradient condition: zero is optimal for the second coefficient because the derivative of the squared-error term at zero is -1, which lies within the interval allowed by the L1 penalty.
Thus, the Lasso solution is:
\boxed{(w_1,w_2)=(2.5,0)}
The second coefficient has been eliminated.
What did we learn?
With the same simplified objective and the same regularization strength:
- Ridge reduced both coefficients.
- Lasso reduced the first coefficient and eliminated the second.
This illustrates why Lasso can produce sparse solutions while Ridge generally retains all features.
The example is deliberately simple, but the same principle applies to larger regression problems.
7. Implementing Ridge and Lasso in Python
Theory becomes much easier to understand when we can test it.
Let's compare both methods using scikit-learn.
We will generate a dataset with 20 input features, but only a few will have genuine predictive value.
This makes the dataset useful for illustrating feature selection.
Step 1: Import the libraries
import numpy as np
import pandas as pd

from sklearn.datasets import make_regression
from sklearn.model_selection import train_test_split
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler
from sklearn.linear_model import Ridge, Lasso
from sklearn.metrics import mean_squared_error, r2_score
Step 2: Generate the dataset
X, y = make_regression(
    n_samples=1000,
    n_features=20,
    n_informative=5,
    noise=20,
    random_state=42
)

X_train, X_test, y_train, y_test = train_test_split(
    X,
    y,
    test_size=0.2,
    random_state=42
)
We created:
- 1,000 observations.
- 20 input features.
- 5 informative features.
- Some random noise.
Only five features contribute to the generated target according to the dataset's construction.
This gives us a useful setting for examining whether regularization reduces unnecessary coefficients.
Step 3: Train both models
ridge_model = make_pipeline(
    StandardScaler(),
    Ridge(alpha=10.0)
)

lasso_model = make_pipeline(
    StandardScaler(),
    Lasso(alpha=10.0, max_iter=10000)
)

ridge_model.fit(X_train, y_train)
lasso_model.fit(X_train, y_train)
Notice that we use StandardScaler before each model.
Feature scaling matters because regularization penalizes coefficient magnitudes. When features have very different scales, the penalty can affect them unevenly.
The pipeline ensures that the scaler is fitted using the training data and then applied consistently to the test data.
The parameter alpha controls the regularization strength in scikit-learn.
It corresponds conceptually to \lambda, although the exact scaling of the objective depends on the implementation.
Step 4: Evaluate the models
models = {
    "Ridge": ridge_model,
    "Lasso": lasso_model
}

results = []

for name, model in models.items():
    predictions = model.predict(X_test)

    mse = mean_squared_error(y_test, predictions)
    r2 = r2_score(y_test, predictions)

    results.append({
        "Model": name,
        "MSE": mse,
        "R2": r2
    })

results_df = pd.DataFrame(results)

print(results_df)
We calculate two evaluation metrics.
Mean Squared Error (MSE) measures the average squared difference between predictions and actual values:
\operatorname{MSE} = \frac{1}{n} \sum_{i=1}^{n}(y_i-\hat{y}_i)^2
Lower MSE is generally better.
The coefficient of determination (R^2) compares the model against a baseline that predicts the mean of the observed targets.
For a standard test set:
- R^2=1 indicates perfect predictions.
- R^2=0 means the model performs like the mean-prediction baseline in terms of squared error.
- R^2<0 means the model performs worse than that baseline.
Higher R^2 is generally better.
Step 5: Count the nonzero coefficients
ridge_coefficients = ridge_model.named_steps["ridge"].coef_
lasso_coefficients = lasso_model.named_steps["lasso"].coef_

print(
    "Ridge nonzero coefficients:",
    np.count_nonzero(ridge_coefficients)
)

print(
    "Lasso nonzero coefficients:",
    np.count_nonzero(lasso_coefficients)
)
Ridge will generally retain all 20 coefficients.
Lasso may set some coefficients to exactly zero.
The number of nonzero coefficients depends on the regularization strength and the dataset. It is not guaranteed to recover exactly five features.
The five informative features are not necessarily the only features that can appear useful in a finite, noisy sample.
Step 6: Inspect the coefficients
coefficients = pd.DataFrame({
    "Feature": [f"x{i}" for i in range(X.shape[1])],
    "Ridge": ridge_coefficients,
    "Lasso": lasso_coefficients
})

print(
    coefficients.round(3).to_string(index=False)
)
This table lets you compare how the two methods treat each feature.
You can also visualize the coefficients using Matplotlib to make the differences easier to see.
The important point is that you can now test the mathematical ideas rather than merely memorizing definitions.
Experiment: change alpha from 10.0 to 1.0 and then to 50.0. Observe how the coefficients and test performance change.
8. How Should You Choose Between Ridge and Lasso?
There is no universally superior method.
The best choice depends on the dataset, the objective, and how the features relate to one another.
Choose Ridge when:
- Many features may contribute useful information.
- You want to reduce the magnitude of coefficients without deliberately eliminating features.
- Predictors are strongly correlated.
- You want a stable, regularized linear model.
Choose Lasso when:
- You suspect that only a subset of features is useful.
- You want a simpler model with fewer nonzero coefficients.
- Feature selection is an important part of the task.
- Interpretability and sparsity matter.
What if both approaches have advantages?
You do not have to choose exclusively between L1 and L2 regularization.
Elastic Net combines both penalties:
J(\mathbf{w}) = \frac{1}{n}\|\mathbf{y}-X\mathbf{w}\|_2^2 + \lambda \left[ \alpha\|\mathbf{w}\|_1 + \frac{1-\alpha}{2}\|\mathbf{w}\|_2^2 \right]
Here, \alpha controls the balance between L1 and L2 penalties.
When \alpha=1, the penalty is L1-only.
When \alpha=0, it is L2-only, subject to the displayed scaling convention. In scikit-learn, ElasticNet uses a parameter named l1_ratio for this balance.
Intermediate values combine the two.
Elastic Net can be particularly useful when features are correlated and we also want a sparse solution.
9. A Practical Warning: Always Validate Your Model
It is tempting to choose the method with the lowest training error.
That is usually not enough.
Regularization deliberately allows some additional training error in exchange for the possibility of better generalization.
A proper comparison should use validation data or cross-validation to select the regularization strength.
For example, you might evaluate several values:
\lambda\in\{0.01,0.1,1,10,100\}
The best value depends on the dataset.
The test set should ideally be reserved for the final evaluation, rather than repeatedly used to tune the model.
Another important consideration is feature scaling.
Since regularization penalizes coefficient magnitudes, features measured in different units can receive different effective treatment unless the data is appropriately prepared.
Finally, neither Ridge nor Lasso automatically solves every form of overfitting. Their effectiveness depends on the data and the assumptions behind the model.
10. Test Your Understanding
Try answering these questions before checking the solutions.
Question 1: The penalty
Which regularization method uses the sum of squared coefficients?
A. Lasso
B. Ridge
C. Both
D. Neither
Answer: B — Ridge.
Ridge uses the L2 penalty:
\sum_{j=1}^{p}w_j^2
Lasso instead uses the L1 penalty:
\sum_{j=1}^{p}|w_j|
Question 2: Feature selection
A model contains 100 features, but you suspect that only a small subset is genuinely useful.
Which method is particularly attractive if you want some coefficients to become exactly zero?
Lasso Regression.
Its L1 penalty can produce sparse coefficient vectors, effectively removing some features from the linear prediction.
However, the selected features may vary with the data and regularization strength, particularly when predictors are correlated.
Question 3: Increasing regularization
What generally happens when you substantially increase the regularization strength?
The model is penalized more strongly for large coefficients.
Ridge generally shrinks its coefficients further towards zero. Lasso generally increases sparsity as the penalty grows.
If regularization becomes too strong, the model may underfit the data.
Question 4: Correlated features
Two input features provide almost identical information.
Which method may be preferable if you want to stabilize the model while retaining both features?
Ridge is often a good starting point.
Its L2 penalty can stabilize coefficient estimates in the presence of correlated features.
Lasso may instead select one feature and suppress another, although the exact outcome depends on the data.
Question 5: Practical implementation
Why do we place StandardScaler before Ridge or Lasso in our Python pipelines?
Feature scaling puts numerical features on comparable scales.
Without scaling, the same coefficient magnitude can have different practical meanings for features measured in different units. This can affect how regularization influences the model.
The scaler must be fitted on the training data only to avoid data leakage.
Final Thoughts
Ridge and Lasso begin with the same objective: build a model that generalizes beyond its training data.
Their difference lies in how they penalize complexity.
Ridge uses squared coefficients and generally keeps every feature, shrinking their influence towards zero.
Lasso uses absolute coefficients and can eliminate some features entirely.
Neither method is automatically better. The correct choice depends on the structure of the data, the relationships between features, and the goals of the analysis.
The deeper lesson is that machine learning is not only about fitting data. It is also about deciding which patterns deserve to survive.
Once you understand regularization, you are better prepared to study gradient descent, statistical learning, model selection, and the optimization techniques behind modern AI.