 NERDICATE
RAG Systems in Python: Build an AI That Can Answer Questions About Your PDFs
Build a RAG system that lets AI answer questions about your PDFs. Learn how to extract text, split documents into chunks, generate embeddings, and retrieve relevant information to produce answers grounded in your own documents. A practical introduction to the technology behind AI-powered document search.
Build a RAG System That Answers Questions About Your PDFs
A retrieval-augmented generation (RAG) system lets a language model answer questions using documents you control. Instead of relying only on what the model learned during training, you retrieve the most relevant passages from your PDFs and provide them to the model as context.
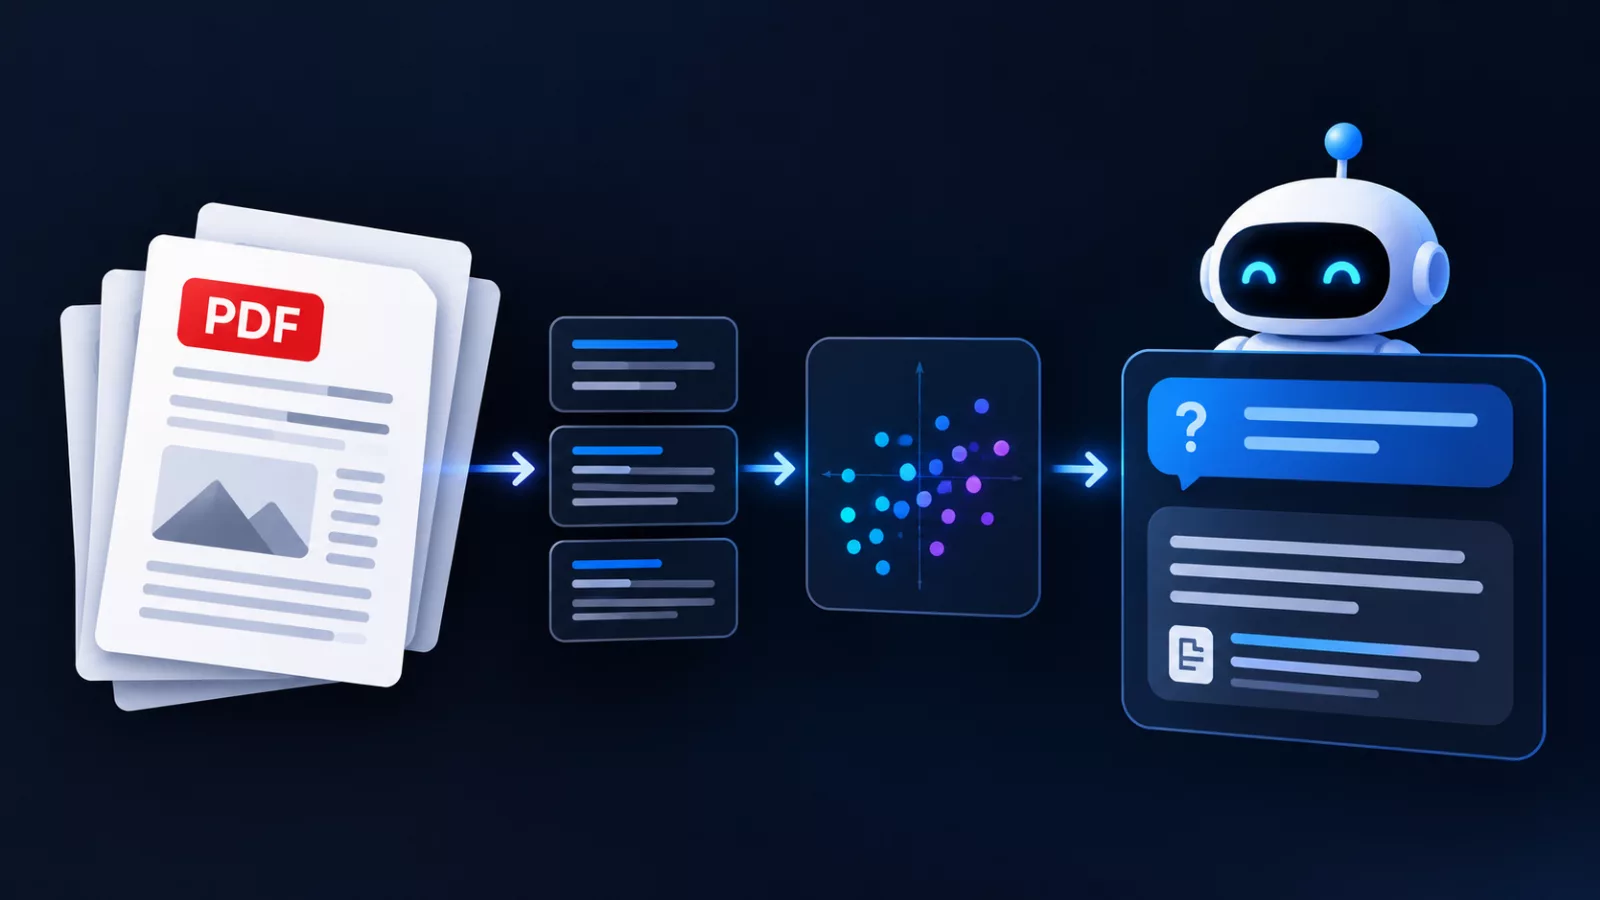
The core pipeline has four stages: extract text, split it into chunks, convert chunks into embeddings, and retrieve the best matches for a query. Each stage can silently damage the final answer, so the real engineering is not “connect an LLM to a PDF” — it is preserving meaning through every transformation.
What RAG actually does
A minimal RAG system follows this flow:
PDFs → text extraction → chunking → embeddings → vector index
                                                        ↓
User question → query embedding → retrieval → LLM answer
At query time, the system embeds the user’s question, searches a vector index for semantically similar chunks, and passes those chunks to the language model as evidence. The model then writes an answer grounded in the retrieved material.
This matters because an LLM does not automatically “look up” your PDFs. It can only use information present in its prompt. Retrieval supplies that evidence; generation turns it into a response.
Step 1: Extract text from PDFs
PDF is a presentation format, not a clean text format. A PDF stores instructions about where to place glyphs, fonts, images, and lines — not necessarily a tidy sequence of paragraphs. Text extraction therefore has to reconstruct reading order, and it will not always succeed.
For text-based PDFs, pypdf is a practical starting point. Its PdfReader exposes pages, and extract_text() returns the textual content of a page.
from pypdf import PdfReader

def extract_pdf_text(path: str) -> list[dict]:
    reader = PdfReader(path)
    pages = []

    for i, page in enumerate(reader.pages):
        text = page.extract_text() or ""
        text = " ".join(text.split())

        if text:
            pages.append({
                "source": path,
                "page": i + 1,
                "text": text,
            })

    return pages
Keep the page number. It is one of the cheapest and most useful pieces of metadata in a RAG system: it lets the assistant cite where an answer came from rather than merely asserting it.
The scanned-PDF problem
If a PDF is a scan, extract_text() may return little or nothing useful. The document contains images of text, not selectable text. You need optical character recognition (OCR), for example Tesseract, often after improving contrast, resolution, and page orientation.
A simple diagnostic:
pages = extract_pdf_text("report.pdf")
empty = sum(1 for p in pages if len(p["text"]) < 40)

print(f"{empty}/{len(pages)} pages produced little or no text")
If many pages are effectively empty, do not build embeddings yet. Fix extraction first. A RAG system cannot retrieve meaning that was never extracted.
Step 2: Chunk the text
Embedding models have input limits, and long passages dilute semantic focus. A 20-page chapter may contain several unrelated ideas; embedding the entire chapter produces one vector that represents all of them poorly.
Chunking divides the document into retrievable units. The goal is not to make chunks as small as possible. It is to make each chunk self-contained enough to be understood while retaining enough surrounding context to be useful.
A common baseline is overlapping character chunks:
def chunk_text(
    text: str,
    chunk_size: int = 1200,
    overlap: int = 200,
) -> list[str]:
    chunks = []
    start = 0

    while start < len(text):
        end = start + chunk_size
        chunk = text[start:end]
        chunks.append(chunk)
        start += chunk_size - overlap

    return chunks
For many document collections, a better default is to split on paragraph or section boundaries first, then merge small pieces until they approach a target size. Fixed-width splitting is easy, but it can cut a sentence, definition, table, or equation in half.
Chunking choices that matter
| Approach | Strength | Risk |
|---|---|---|
| Fixed-size characters | Simple and predictable | Breaks sentences and ideas |
| Paragraph-based | Preserves natural units | Some paragraphs may be too long or too short |
| Heading-aware splitting | Keeps sections together | Depends on reliable PDF structure |
| Recursive splitting | Balances size and structure | More parameters to tune |
| Semantic chunking | Groups related content | More complex and computationally costly |
A practical starting configuration is 800–1,200 characters per chunk with 10–20% overlap. Then inspect real retrieved chunks. If answers frequently lack context, increase chunk size or overlap. If retrieval returns broad, unfocused passages, reduce chunk size or improve section-aware splitting.
Step 3: Create embeddings
An embedding is a numerical vector that represents the semantic content of a text passage. Similar meanings produce nearby vectors, even when the wording differs.
For example, these questions should ideally be close in embedding space:
- “How does the model handle missing data?”
- “What happens when values are absent from the dataset?”
They use different words, but they ask about the same concept. That is the advantage over naive keyword matching.
Sentence Transformers provides a straightforward way to compute embeddings locally. Its models convert text into dense vectors and support similarity computation between embeddings.
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("all-MiniLM-L6-v2")

def embed_texts(texts: list[str]) -> list[list[float]]:
    return model.encode(
        texts,
        normalize_embeddings=True,
        show_progress_bar=True,
    ).tolist()
Normalisation is useful when you plan to use cosine similarity. For two vectors \mathbf{a} and \mathbf{b}, cosine similarity is:
\cos(\theta) = \frac{\mathbf{a} \cdot \mathbf{b}}{\|\mathbf{a}\|\|\mathbf{b}\|}
If both vectors are normalised, so that \|\mathbf{a}\| = \|\mathbf{b}\| = 1, this simplifies to:
\cos(\theta) = \mathbf{a} \cdot \mathbf{b}
Use the same embedding model for documents and queries. Embeddings from different models occupy different vector spaces; comparing them directly is usually meaningless.
Step 4: Store vectors and retrieve
For a small personal knowledge base, a vector index does not need to be complicated. FAISS is a library for efficient similarity search and clustering of dense vectors, including nearest-neighbour search over embeddings.
import faiss
import numpy as np
from sentence_transformers import SentenceTransformer

class PdfRagIndex:
    def __init__(self, embedding_model: str = "all-MiniLM-L6-v2"):
        self.model = SentenceTransformer(embedding_model)
        self.chunks: list[dict] = []
        self.index = None

    def add_documents(self, pdf_paths: list[str]):
        records = []

        for path in pdf_paths:
            for page in extract_pdf_text(path):
                for chunk in chunk_text(page["text"]):
                    records.append({
                        "source": page["source"],
                        "page": page["page"],
                        "text": chunk,
                    })

        texts = [record["text"] for record in records]

        vectors = np.array(
            self.model.encode(texts, normalize_embeddings=True),
            dtype="float32",
        )

        self.chunks = records
        self.index = faiss.IndexFlatIP(vectors.shape)[1]
        self.index.add(vectors)

    def search(self, query: str, k: int = 5) -> list[dict]:
        query_vector = np.array(
            [self.model.encode(query, normalize_embeddings=True)],
            dtype="float32",
        )

        scores, ids = self.index.search(query_vector, k)

        results = []
        for score, i in zip(scores, ids):
            result = self.chunks[i].copy()
            result["score"] = float(score)
            results.append(result)

        return results
IndexFlatIP performs exact inner-product search. For normalised vectors, that ranks results by cosine similarity. It is a strong default for small and medium collections; FAISS also provides approximate indexes for larger datasets where memory, latency, and accuracy must be balanced.
Step 5: Turn retrieval into an answer
Retrieval alone does not answer the question. The final prompt should make the evidence visible, restrict the model to that evidence, and require citations.
def build_prompt(question: str, results: list[dict]) -> str:
    context = "\n\n".join(
        f"[{i + 1}] Source: {result['source']}, page {result['page']}\n{result['text']}"
        for i, result in enumerate(results)
    )

    return f"""Answer the question using only the context below.

If the context does not contain enough information, say so clearly.
Cite the relevant sources using their numbered references.

Context:
{context}

Question:
{question}

Answer:"""
A useful answer should distinguish three cases:
- The retrieved context contains a direct answer.
- The context contains partial evidence, but the conclusion requires interpretation.
- The context does not contain enough information.
The third case is not a failure. “I cannot find this in the provided documents” is often the most valuable output a RAG system can produce.
Evaluation: the part people skip
A RAG demo can look impressive while retrieving the wrong passages. Before trusting it, build a small evaluation set of real questions and expected source passages.
Measure at least:
- Retrieval quality: Did the correct chunk appear in the top k results?
- Answer faithfulness: Does the answer follow from the retrieved context?
- Citation accuracy: Do the cited pages actually support the claim?
- Refusal behaviour: Does the system admit insufficient evidence instead of inventing an answer?
- Robustness: Does it handle paraphrases, typos, multi-part questions, and ambiguous terms?
For retrieval, a simple metric is recall@k:
\text{recall@}k = \frac{\text{number of relevant chunks retrieved in top } k} {\text{total number of relevant chunks}}
If the correct evidence is not retrieved, no prompt template or powerful LLM can reliably repair the problem. Retrieval is the foundation; generation is the presentation layer.
Common failure modes
| Failure | Symptom | Likely fix |
|---|---|---|
| Poor extraction | Empty pages, jumbled text, broken tables | Use OCR, layout-aware parsing, or a different extractor |
| Bad chunk boundaries | Answers miss context or cite fragments | Use section-aware or recursive chunking |
| Wrong embedding model | Paraphrases do not retrieve well | Test domain-specific or higher-quality embedding models |
| Too few retrieved chunks | The model lacks evidence | Increase k, improve chunking, or add reranking |
| Too many retrieved chunks | Context becomes noisy and expensive | Use reranking and stricter relevance thresholds |
| Hallucination | Confident answer without support | Require citations and allow explicit refusal |
| Stale index | New PDFs are ignored | Rebuild or incrementally update the index |
Where to improve first
If your system gives weak answers, improve components in this order:
- Extraction: Verify that the text is complete and readable.
- Chunking: Check whether retrieved chunks contain enough context.
- Retrieval: Test whether the correct source appears for known questions.
- Prompting: Require citations, prohibit unsupported claims, and permit refusal.
- Reranking: Add a cross-encoder reranker after initial vector retrieval.
- Evaluation: Expand a question set based on real user queries.
A cross-encoder reranker can be particularly effective. Vector retrieval quickly narrows thousands of chunks to, say, 50 candidates; a reranker then scores each query–chunk pair more carefully and returns the strongest few.
The essential idea
RAG is not magic context injection. It is an information-retrieval system with a language model at the end.
The quality of its answers is bounded by the quality of its evidence. Extract the text accurately, preserve meaningful boundaries, embed comparable units, retrieve with a measurable objective, and force the model to show its sources. Do that, and a PDF question-answering system becomes genuinely useful rather than merely plausible.